Transformer란?
Transformer의 Encoder/Decoder 구조를 Multi-Head Attention, Masked Self-Attention, Cross Attention, Add & Norm 중심으로 정리한다.
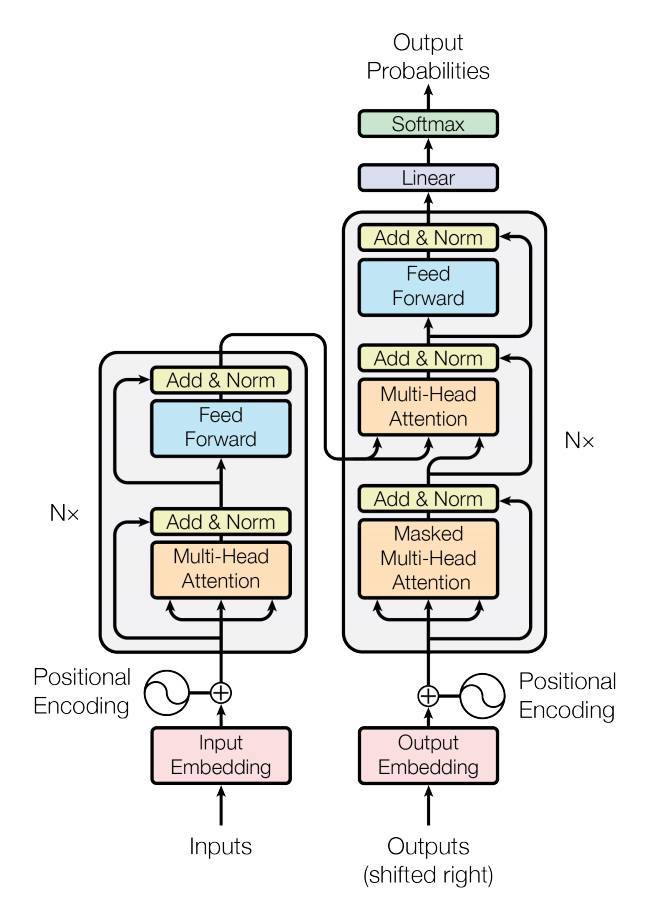
Transformer의 Encoder/Decoder 구조를 Multi-Head Attention, Masked Self-Attention, Cross Attention, Add & Norm 중심으로 정리한다.
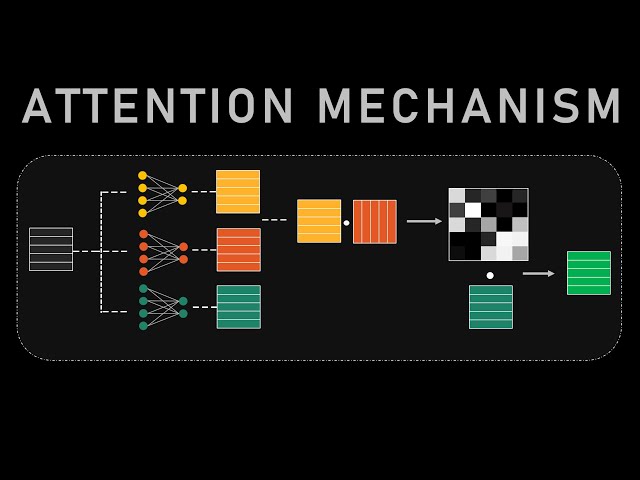
내적과 가중합이라는 텐서 연산에서 출발해 Attention의 Query-Key-Value 계산 과정을 단계별로 따라가고, Self-Attention과 Cross-Attention의 차이, 그리고 순서 정보를 주입하는 Positional Encoding의 필요성까지 정리한다.
Claude Code의 사용법과 주요 기능을 상세히 설명합니다. Normal, Auto-Accept, Plan 모드의 차이점과 권장 워크플로우를 안내하며, CLAUDE.md를 통한 프로젝트 규칙 정의 방법을 다룹니다. 컨텍스트 관리, 프롬프팅 기법, Skills 및 SubAgent 활용법, 그리고 Hooks와 단축키 등 효율적인 개발을 위한 다양한 팁과 모범 사례를 제공합니다.